AI assistants, document OCR, and monitoring systems.
Three services, each with a fixed scope. Pick the one that is breaking: an assistant that guesses, OCR that scrambles spreads, or a monitor that reports an empty market when the source is down.
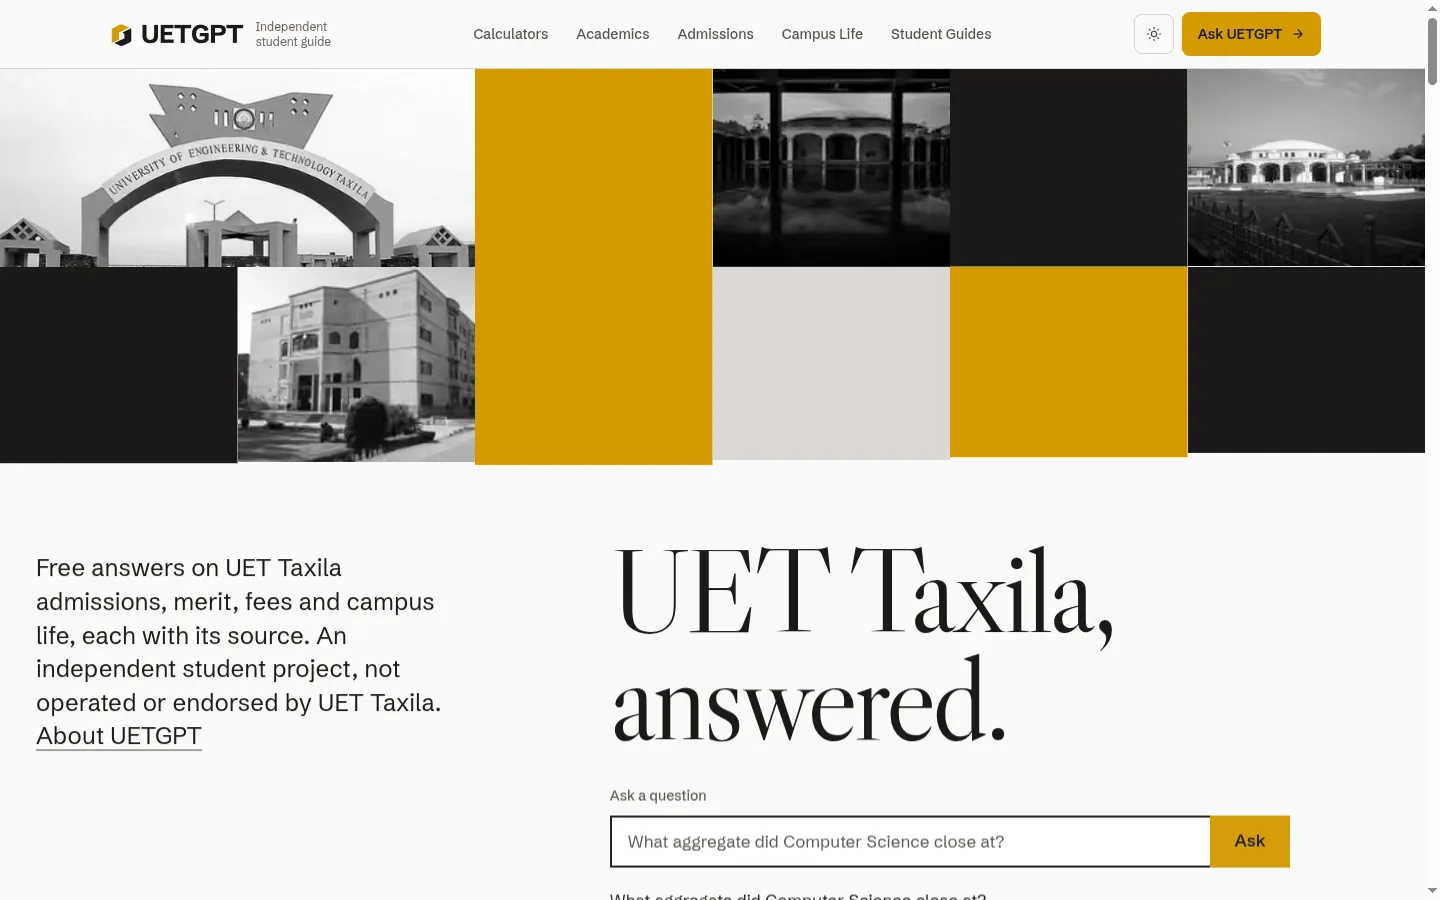
AI Assistants & Production RAG Systems
Turn documents and knowledge bases into grounded assistants
Retrieval-augmented generation (RAG) assistants over your documentation or website, with reranking, citations and model fallback. When retrieval finds nothing, the assistant is told to refuse; weak matches get a hedged answer. I test where that still goes wrong.
Next.js 15, Convex Vector Search, Vercel AI SDK, Groq / GeminiUET GPT (live and unofficial)
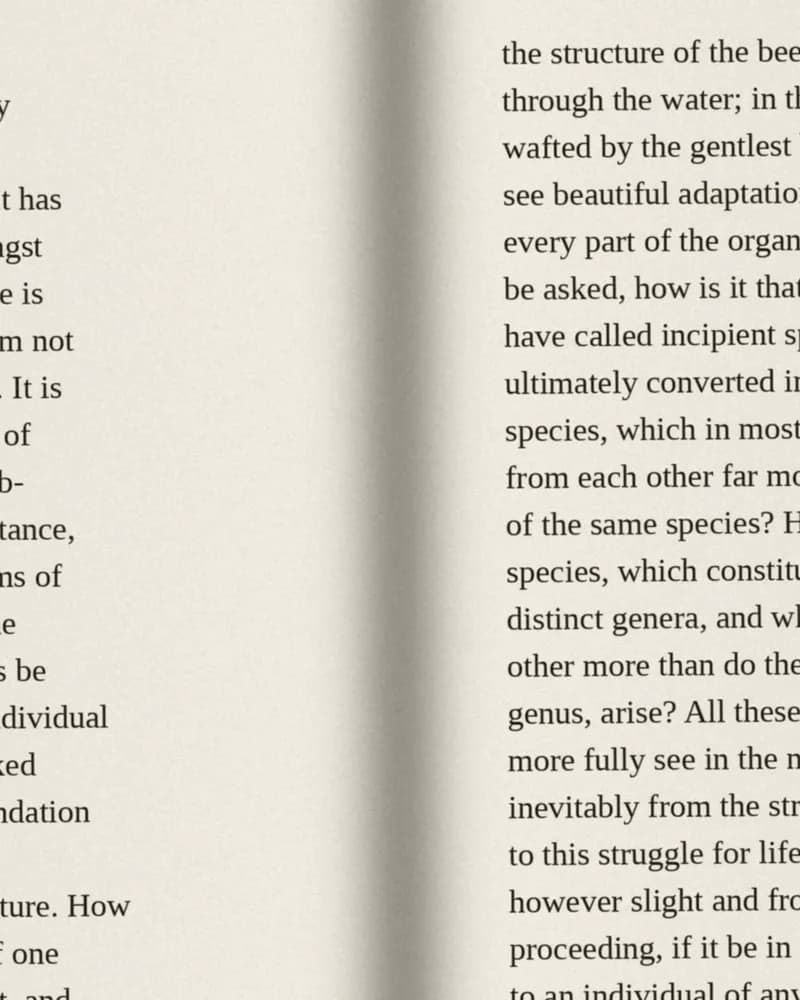
Document OCR & Processing Pipelines
Layout-aware text extraction for scans, spreads and PDFs
Deterministic text and table extraction from scanned books, two-page spreads, and multi-column PDFs. Splits spreads at the gutter, restores reading hierarchy, and scores progress against hand-transcribed test sets.
Python 3.12, RapidOCR / ONNX, PyMuPDF, SQLite WALB.L.A.S.T., 914 collected tests
A feed that won’t load looks exactly like “no new jobs”.
Web Scraping, Monitoring & Alerting
Fail-closed scrapers and alerting automation
Scrapers and multi-source ETL pipelines in Python with HTTP/2 concurrency, Pydantic schema validation, and SQLite in WAL mode. Sources that fail to load correctly are skipped and recorded as degraded with the reason, instead of silently sending an empty result.
Python 3.12, httpx (HTTP/2), Pydantic, SQLite WAL, SMTPMarketplace Monitor, 304 collected tests